AI solutions
AI infrastructure, built and run for you.
GPU servers and clusters for training, fine-tuning and inference, on NVIDIA or AMD, with the network, storage and management software to keep them busy.
Designed, built and supported by our own HPC/AI engineers.
Sized to your models
Tested before it ships
Supported for the life of the system
Train, fine-tune and serve.
Systems sized to your models, your data and your budget, from a single GPU server to a full training cluster.
Training clusters
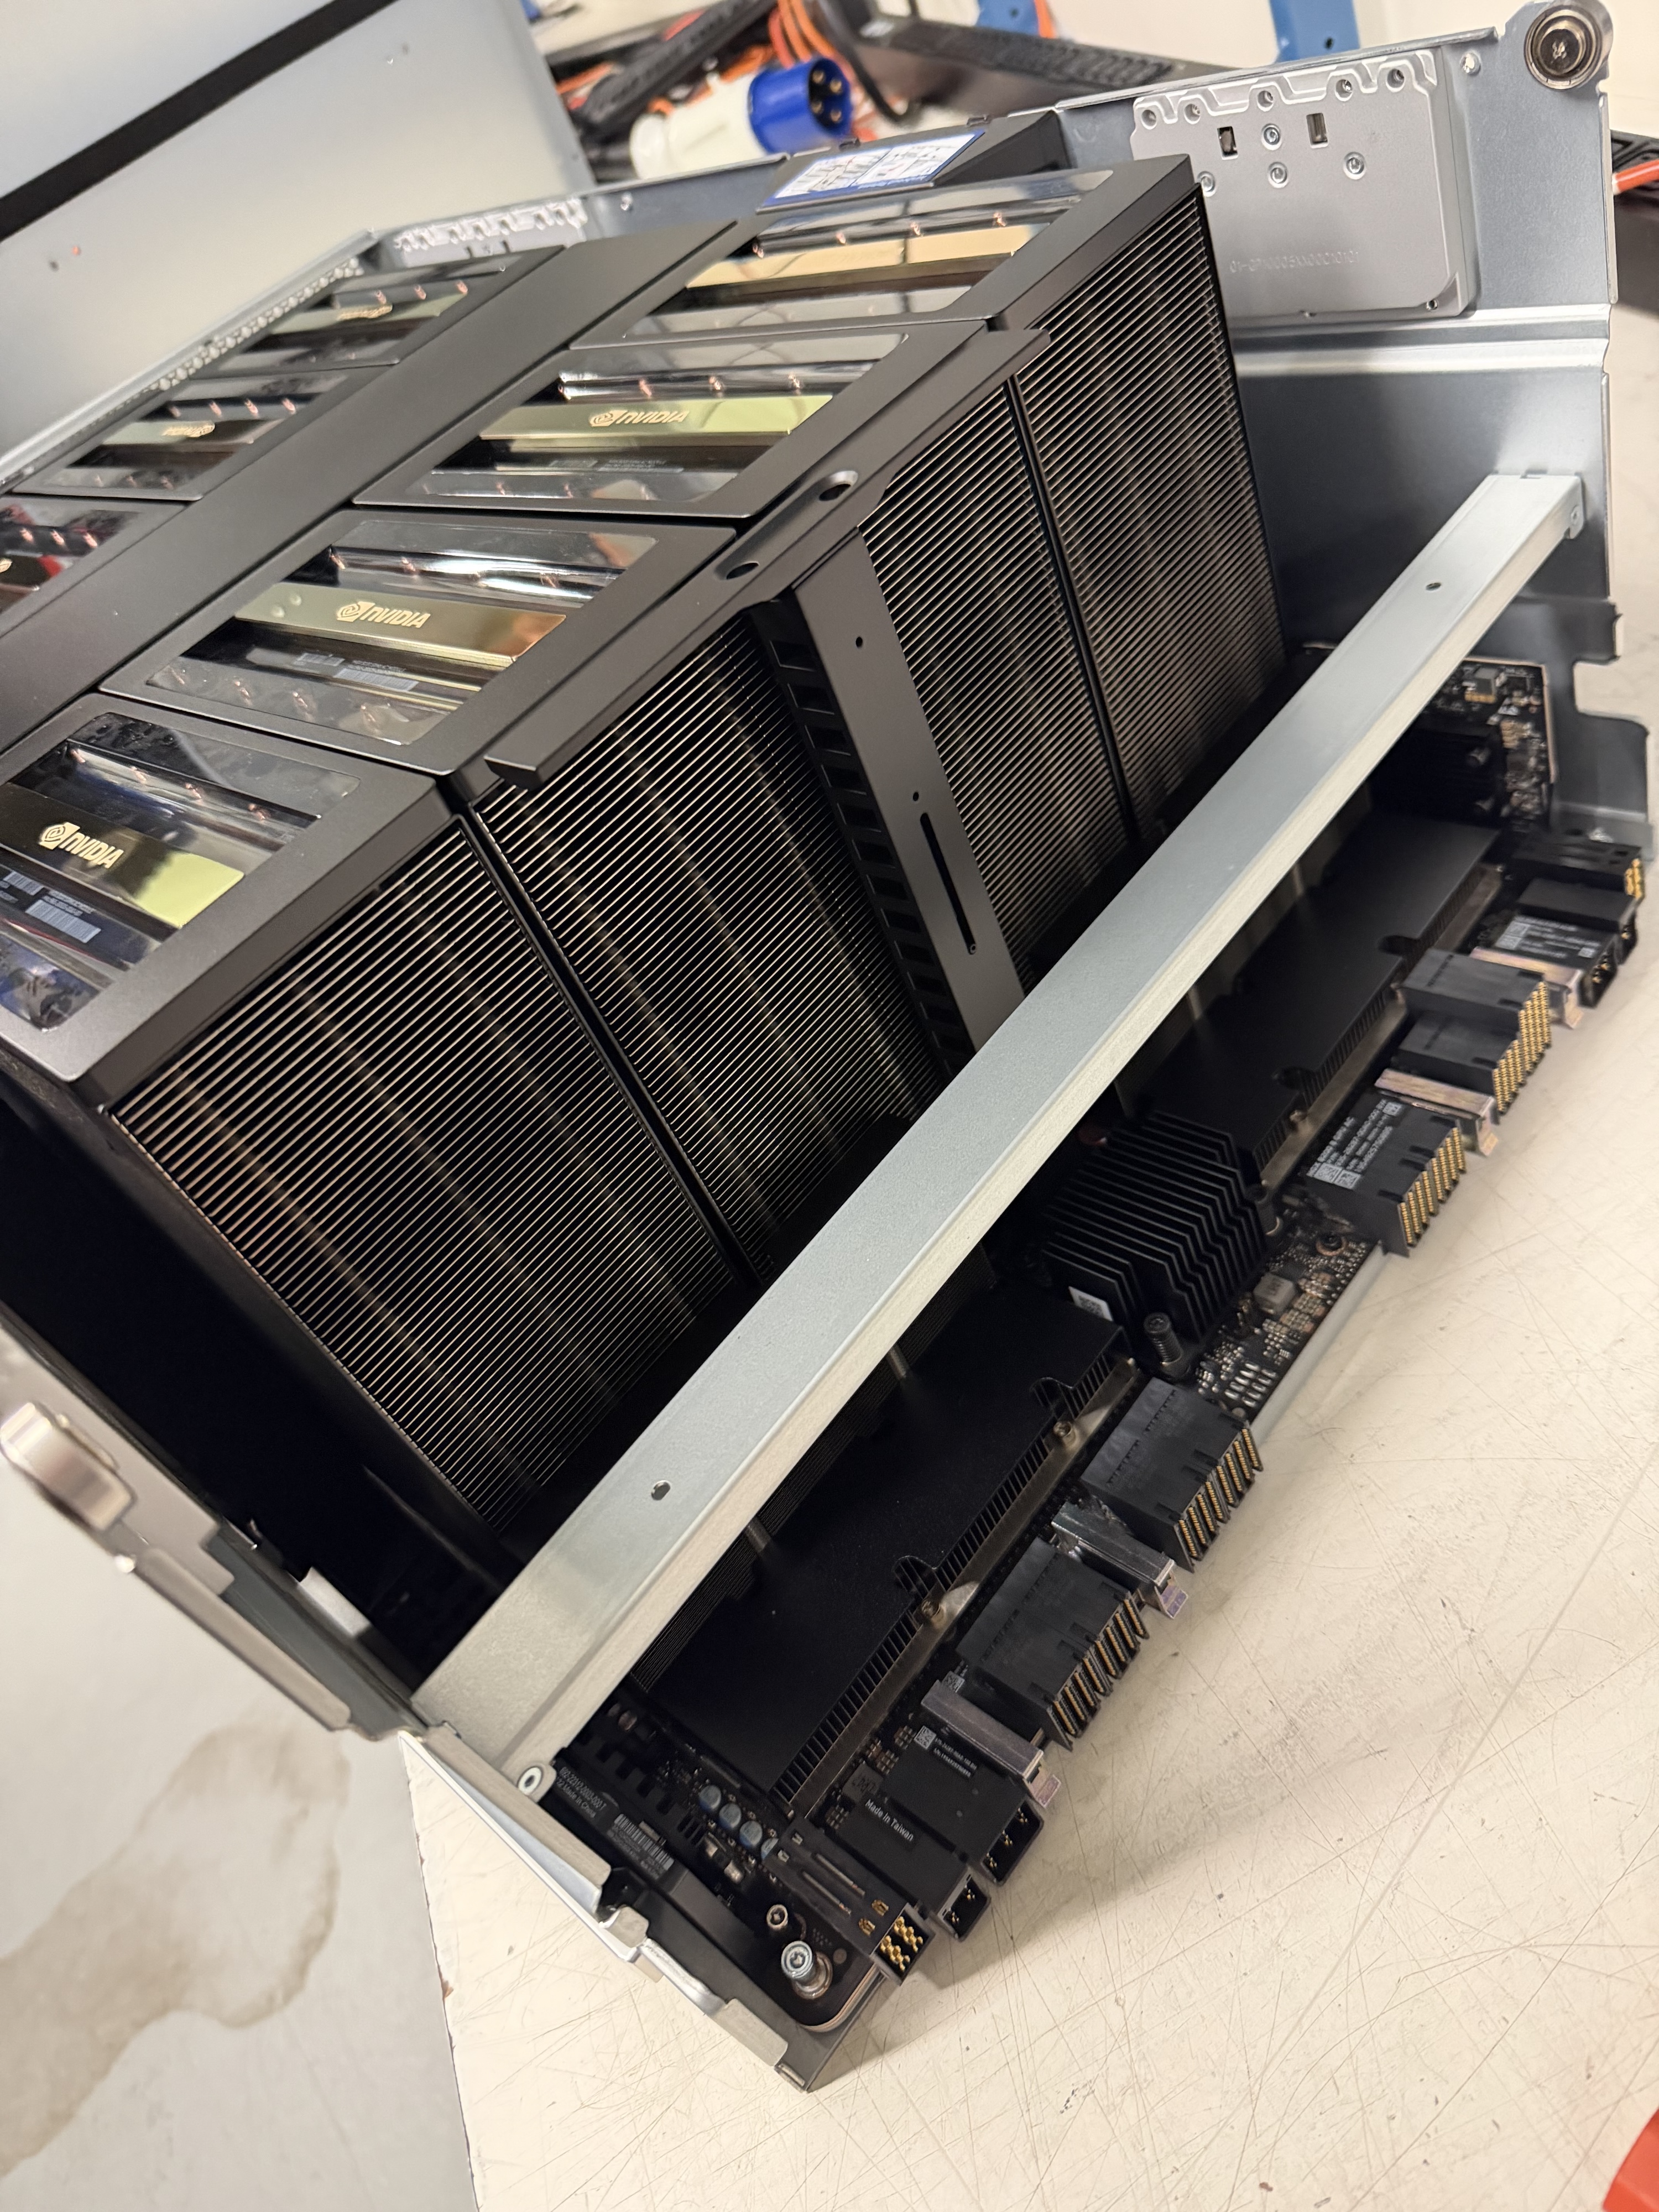
The latest NVIDIA data center GPUs, Hopper and Blackwell, or AMD Instinct accelerators, connected by a high-speed fabric and shared storage so training scales across many nodes.
Inference and fine-tuning
GPU servers sized to the models you run, from a single server for one team to a pool shared across a department.
Development systems
GPU workstations and smaller servers for building and testing models before they move to the cluster.
Servers and workstations →GPU platforms
The right GPUs for your software.
We’re partners of both NVIDIA and AMD, so we build on whichever fits your frameworks and workloads.
NVIDIA
Hopper and Blackwell systems, including 8-GPU HGX B200 and B300, for large training and inference work, plus smaller GPU servers and workstations.
AMD
AMD Instinct accelerators for teams whose software runs on AMD’s ROCm platform, alongside AMD EPYC processors across the rest of your cluster.
Not sure which fits?
Tell us about your models, frameworks and budget, and we’ll recommend a configuration.
Talk to usNetworking
The fabric decides how far you scale.
We shipped our first InfiniBand system, on SDR, in 2003, and we design high-speed Ethernet fabrics too.
InfiniBand
Low-latency fabrics for multi-node training, designed with the right topology and level of oversubscription for the jobs you run.
High-speed Ethernet
Ethernet fabrics for inference, storage and mixed workloads, sized to how your systems actually communicate.
Planned as one system
We design the fabric together with the GPUs and storage, so the network is part of the plan from day one, not an afterthought.
Inside an AI system
Built so no GPU waits.
GPUs that work as one
NVLink and NVSwitch connect all eight GPUs in a server directly, so they share data without a detour through the CPU.
A fabric that keeps pace
Large training jobs share results after every step, so the network between servers decides how fast the whole job runs.
No extra copies
With GPUDirect RDMA, data moves from GPU memory straight to the network adapter and into GPUs on other servers, skipping the CPU and system memory.
Storage that keeps up
Parallel storage streams from every server at once, so expensive GPUs spend their time computing, not waiting for data.
Storage and software
Keep the GPUs busy.
Fast storage to feed them, the software to run on them, and the tools to manage it all.
AI software, ready to run
We can pre-install and test the stack your team uses: GPU drivers, CUDA and NCCL (or ROCm on AMD), frameworks like PyTorch, TensorFlow and JAX, Hugging Face libraries, Jupyter notebooks, and container tools like Apptainer.
BeeGFS storage
A parallel file system that serves training data to every node at once. We’re a Platinum BeeGFS partner.
BeeGFS storage →ClusterVisor
Provision nodes, manage Slurm and track every NVIDIA GPU’s usage, memory and power, from one place.
ClusterVisor →JobVisor
Researchers submit jobs and launch interactive sessions through simple web forms, without learning Slurm.
JobVisor →Run it with confidence
Managed from day one.
Included with every cluster
Our cluster management software comes installed and configured on every cluster we build: monitoring, alerts, provisioning, job visibility and rack diagrams across every node, including each NVIDIA GPU’s usage, memory and power. It supports SELinux in enforcing mode, and its enhanced security option adds full disk encryption and FIPS mode.
Explore ClusterVisor →Optional
Managed services
Want us to run it too? Our engineers monitor, patch, tune and support your cluster, with coverage and pricing built around how you use it.
See managed services →Which GPUs do you offer?
NVIDIA Hopper and Blackwell systems, including 8-GPU HGX B200 and B300, plus smaller GPU servers and workstations. AMD Instinct systems are also available for teams whose software runs on ROCm.
Will our AI software be ready to use?
Yes. We can pre-install and test GPU drivers, CUDA or ROCm, and frameworks like PyTorch, TensorFlow and JAX before the system ships, so your team can start working right away.
Do we need InfiniBand, or will Ethernet do?
It depends on how you’ll use the system. Training across many nodes benefits most from a low-latency fabric like InfiniBand, while inference and single-server work often run well on high-speed Ethernet. We’ll recommend the right fit for your workloads.
How soon can we get GPUs?
It depends on the system and current GPU supply. Ask us which pre-configured systems are available for relatively quick shipping.
Can our data center handle an 8-GPU system?
8-GPU systems need significant power and cooling. We plan rack layout, power distribution and cooling around your facility, so the system fits the space and power you have.
Can you add GPU nodes to our existing cluster?
Yes. Whoever built your cluster, we can add GPU nodes and bring them under ClusterVisor, so everything is managed in one place.
Let’s plan your AI system.
Engineering the future of HPC and AI
info@advancedclustering.com(866) 802-82223148 Roanoke Road, Kansas City, MO 64111